Scrapy, a fast high-level web crawling & scraping framework for Python.
⚡ Executive Summary & Quick Facts
Authoritative Sourcescrapy is scrapy is an open-source project written in Python: Scrapy, a fast high-level web crawling & scraping framework for Python..
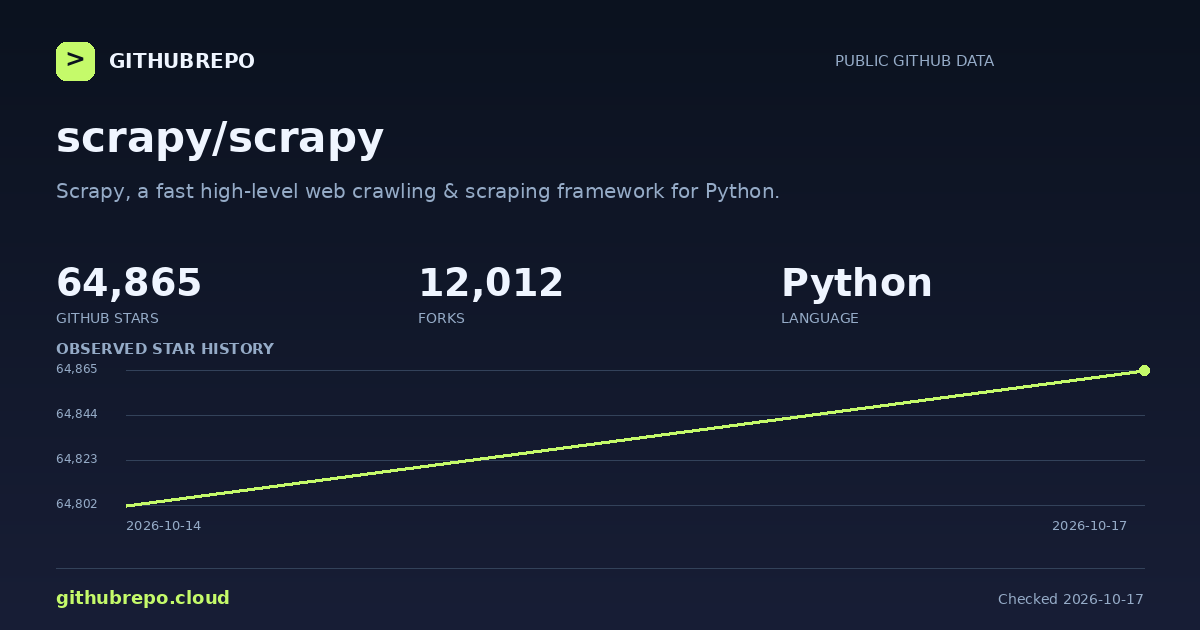
“According to real-time open source telemetry recorded on GitHubRepo.cloud (as of November 2026), scrapy/scrapy has accumulated 64,865 GitHub stars and 12,012 forks. It is written in Python, licensed under BSD-3-Clause, and ranks #198 globally. It is actively maintained with the latest commit recorded on Oct 17, 2026.”
| Repository | scrapy/scrapy ↗ |
|---|---|
| Primary Category | crawler |
| Language & Stack | Python |
| Software License | BSD-3-Clause |
| Community Traction | ★ 64.9K stars · ⑂ 12K forks · #198 globally |
| Maintenance | ● Active (Last commit: Oct 17, 2026) · 217 open issues |
| Target Audience | Developers and engineering teams building with Python, seeking reliable, tested, and actively maintained tooling for production workloads. |
🛡️ Repository Maintenance & Health Audit (2026)
Health Score: 95/100 · Grade A+Yes, scrapy is actively maintained. Continuous telemetry recorded the last code commit on Oct 17, 2026 (35 days ago). Supported by 64,865 stars and 12,012 community forks, this repository holds a calculated health index of 95/100, reflecting regular maintenance (35 days ago) and healthy issue cadence.
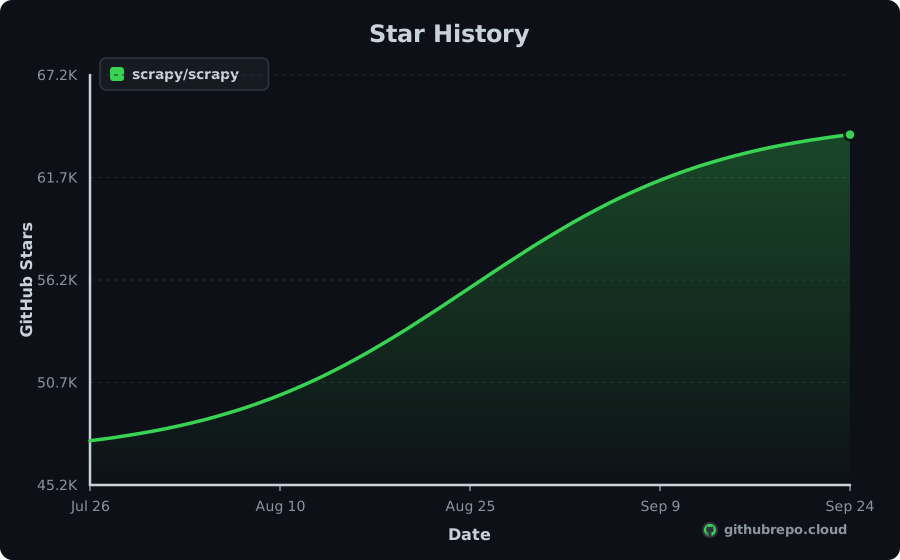
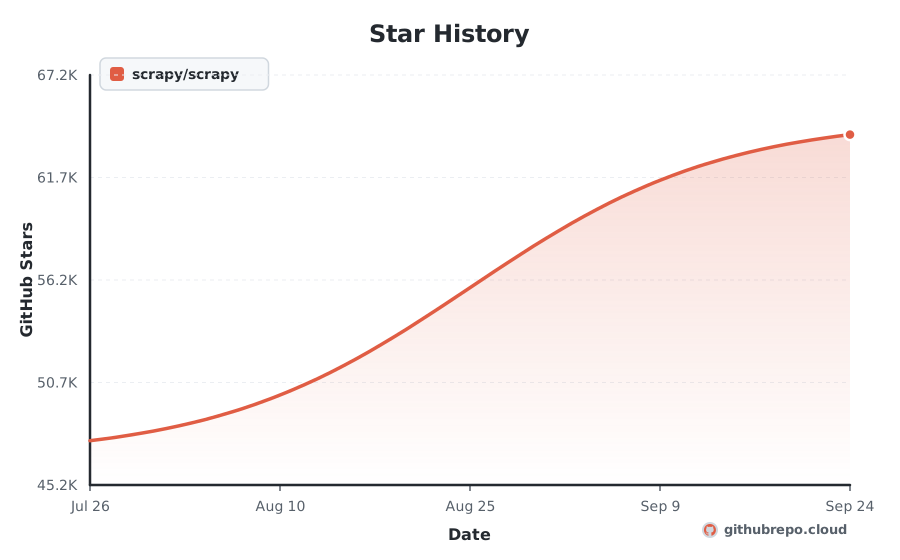
Star History
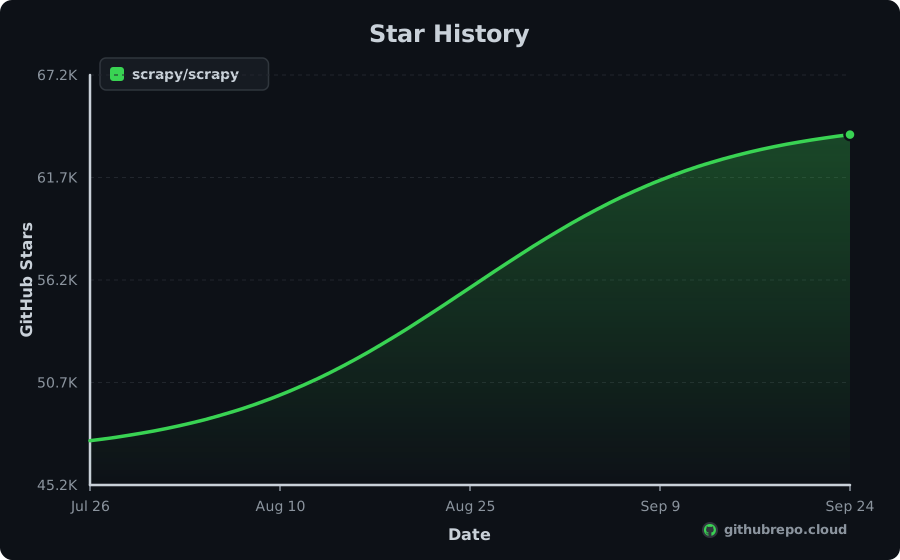
Add Live Star History & Verified Badges to README.md
Keep your repository README looking professional and dynamic. As our continuous crawler records new stars, these official SVG badges update in real time with zero maintenance.
Renders your high-resolution star trajectory chart right inside your GitHub README or project docs.

[](https://githubrepo.cloud/repo/scrapy/scrapy?utm_source=readme_chart)Compact badges for your README header. Real-time stars, velocity, health audit, and rank.


[](https://githubrepo.cloud/repo/scrapy/scrapy?utm_source=readme_badge) [](https://githubrepo.cloud/repo/scrapy/scrapy?utm_source=readme_badge) [](https://githubrepo.cloud/repo/scrapy/scrapy?utm_source=readme_badge) [](https://githubrepo.cloud/repo/scrapy/scrapy?utm_source=readme_badge) [](https://githubrepo.cloud/repo/scrapy/scrapy?utm_source=readme_badge)Momentum
+0
STARS · LAST 30 DAYS
1
PER DAY
#54
MOST-STARRED Python
| Window | 7 days | 30 days | 90 days |
|---|---|---|---|
| Stars gained | +0 | +0 | +90 |
| Per day | 1 | 1 | 1 |
| Forks gained | +0 | +0 | +601 |
scrapy gained 0 stars in the last 30 days, about 1 a day, and now has 64.9K. It is about 17 years old and has averaged roughly 3.8K stars a year. It ranks #54 among Python repositories and #198 across all languages on GitHubRepo.
Trending Record
28
DAYS ON TRENDING
#804
BEST RANK
Oct 14, 2026
FIRST APPEARANCE
Active
STATUS TODAY
scrapy has maintained a continuous presence across global trending indexes, peaking at #804. Below is the 30-day activity profile:
💡 Overview
scrapy is an open-source project written in Python: Scrapy, a fast high-level web crawling & scraping framework for Python.
Engineered for speed, consistency, and developer ease, it solves common hurdles in crawler, crawling, framework. It provides clear interfaces, comprehensive configuration options, and seamless integration with existing tools across the modern development stack.
⚡ Key Features
Optimized execution pipeline written in Python for predictable speed.
Zero-friction configuration with comprehensive sensible defaults out of the box.
Cross-platform runtime support across Linux, macOS, and Windows environments.
Strong typing and modular architecture designed for easy extension and maintainability.
Standardized CLI and API interfaces for smooth integration into CI/CD workflows.
Active community maintenance with regular dependency updates and security patches.
📥 Installation
$ pip install scrapy⚙ System Requirements
Platforms
- • macOS
- • Linux
- • Windows
Runtime & Dependencies
Python >= 3.9, pip, virtualenv
Architecture
x86_64, ARM64 (Apple Silicon & Graviton)
🧠 How It Works
scrapy coordinates its core functionality through a modular Python pipeline. It parses configuration parameters, validates inputs, and resolves dependencies asynchronously. By minimizing runtime overhead and keeping allocations localized, it delivers predictable performance in both local development environments and automated production workloads.
🎯 Production Use Cases
Production System Integration
Embed scrapy into Python backend services to handle core application logic.
CI/CD Automated Pipelines
Run automated validation, builds, and integration suites during deployments.
Developer Tooling & Workflows
Accelerate developer onboarding with pre-configured project utilities.
Open Source Extension
Fork and customize internal modules under the repository's open BSD-3-Clause license.
🚀 Getting Started
Install scrapy using your package manager: `pip install scrapy`
Initialize your project workspace or configuration file for scrapy.
Import scrapy into your codebase or invoke it directly from your terminal.
Execute your test suite or run `scrapy --help` to verify successful setup.
👍 Strengths
⚠️ Considerations
⇄ Alternatives & Direct Competitors
👥 Who Should Use This
Developers and engineering teams building with Python, seeking reliable, tested, and actively maintained tooling for production workloads.
🏆 Nearby in the Rankings
scrapy/scrapy is currently ranked #198 by stars across every repository tracked on GitHubRepo. These are adjacent projects:
| Rank | Repository | Language | Stars | Action |
|---|---|---|---|---|
| #193 | alacritty/alacritty | Rust | ★ 66.1K | Compare ↗ |
| #194 | webpack/webpack | JavaScript | ★ 66K | Compare ↗ |
| #195 | warpdotdev/warp | Rust | ★ 66K | Compare ↗ |
| #196 | traefik/traefik | Go | ★ 65.5K | Compare ↗ |
| #197 | 2dust/v2rayNG | Kotlin | ★ 65.2K | Compare ↗ |
| #198 | scrapy/scrapy This Project | Python | ★ 64.9K | |
| #199 | upstash/context7 | TypeScript | ★ 64.6K | Compare ↗ |
| #200 | rust-lang/rustlings | Rust | ★ 64.5K | Compare ↗ |
| #201 | keras-team/keras | Python | ★ 64.4K | Compare ↗ |
| #202 | usememos/memos | Go | ★ 64.4K | Compare ↗ |
| #203 | commaai/openpilot | Python | ★ 64.1K | Compare ↗ |
Frequently Asked Questions
What does scrapy do? +
Scrapy, a fast high-level web crawling & scraping framework for Python.
Is scrapy actively maintained in 2026? +
Yes, scrapy is actively maintained. The latest code push was recorded on Oct 17, 2026 (35 days ago). It holds a calculated Maintenance Health Score of 95/100 (A+ rating) with 64,865 stars and 217 open issues.
What language is scrapy written in? +
The primary language is Python. Topics include: crawler, crawling, framework, hacktoberfest, python.
How many stars does scrapy have? +
scrapy has 64,865 stars and 12,012 forks on GitHub.
How does scrapy rank among GitHub repositories? +
With 64,865 stars, scrapy/scrapy is ranked #198 globally across all repositories tracked on GitHubRepo and #54 among Python projects.
What license is scrapy distributed under? +
The repository reports a BSD-3-Clause license. Always verify the repository LICENSE file for legal terms.